Hi, I’m Chanyoung Chung, an Integrated M.S. & Ph.D. Student of School of Computing at KAIST. I’m a member of the Big Data Intelligence lab led by Professor Joyce Jiyoung Whang.
My current research interests are graph machine learning, graph neural networks, and knowledge graphs.
Warning
Problem: The current name of your GitHub Pages repository ("Solution: Please consider renaming the repository to "
http://".
However, if the current repository name is intended, you can ignore this message by removing "{% include widgets/debug_repo_name.html %}" in index.html.
Action required
Problem: The current root path of this site is "baseurl ("_config.yml.
Solution: Please set the
baseurl in _config.yml to "Education
-
 Korea Advanced Institute of Science and Technology (KAIST)Integrated M.S. & Ph.D. Student in School of ComputingMar. 2021 - present
-
B.S. in School of Computing & Department of Mathematical Sciences (Double Major)Mar. 2017 - Feb. 2021
Selected Publications (view all )
Ask KG Agent: A Multi-Agent Framework for Code Localization Using Code and Knowledge Graphs
Chanyoung Chung, Jeemin Kim, Joyce Jiyoung Whang
Annual Conference on Neural Information Processing Systems (NeurIPS) 2026
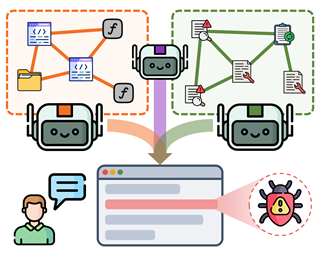
Mapping software issue descriptions to relevant code segments, a task known as code localization, is a primary bottleneck in automated software engineering. While recent attempts have automated it using code graphs that capture syntax-level dependencies among code elements, including functions and modules, their code-centric approaches often overlook the design rationales and prior fix patterns present in a codebase's development history, such as pull requests and commits. We propose Co-Locator, a collaborative multi-agent code localization framework that integrates code graphs reflecting functional dependencies and knowledge graphs constructed from triplets capturing design rationales and past code modifications scattered across the development history. During localization, a Code Graph (CG) agent explores functional hierarchies and consults a Knowledge Graph (KG) agent to gather insights into developer intents and prior bug fixes. Combined with a Retriever agent that assists CG and KG agents, Co-Locator leverages a holistic view of the code's functional and historical context, considering what the code implements and how it was changed, to identify locations to fix. Experiments show that Co-Locator significantly outperforms 12 state-of-the-art baseline methods.
Ask KG Agent: A Multi-Agent Framework for Code Localization Using Code and Knowledge Graphs
Chanyoung Chung, Jeemin Kim, Joyce Jiyoung Whang
Annual Conference on Neural Information Processing Systems (NeurIPS) 2026
Mapping software issue descriptions to relevant code segments, a task known as code localization, is a primary bottleneck in automated software engineering. While recent attempts have automated it using code graphs that capture syntax-level dependencies among code elements, including functions and modules, their code-centric approaches often overlook the design rationales and prior fix patterns present in a codebase's development history, such as pull requests and commits. We propose Co-Locator, a collaborative multi-agent code localization framework that integrates code graphs reflecting functional dependencies and knowledge graphs constructed from triplets capturing design rationales and past code modifications scattered across the development history. During localization, a Code Graph (CG) agent explores functional hierarchies and consults a Knowledge Graph (KG) agent to gather insights into developer intents and prior bug fixes. Combined with a Retriever agent that assists CG and KG agents, Co-Locator leverages a holistic view of the code's functional and historical context, considering what the code implements and how it was changed, to identify locations to fix. Experiments show that Co-Locator significantly outperforms 12 state-of-the-art baseline methods.
FIETA: Few-Shot Inductive Knowledge Graph Completion via Task-Aware Graph Neural Networks
Chanyoung Chung, Minsung Hwang, Joyce Jiyoung Whang
ACM Conference on Information and Knowledge Management (CIKM) 2026
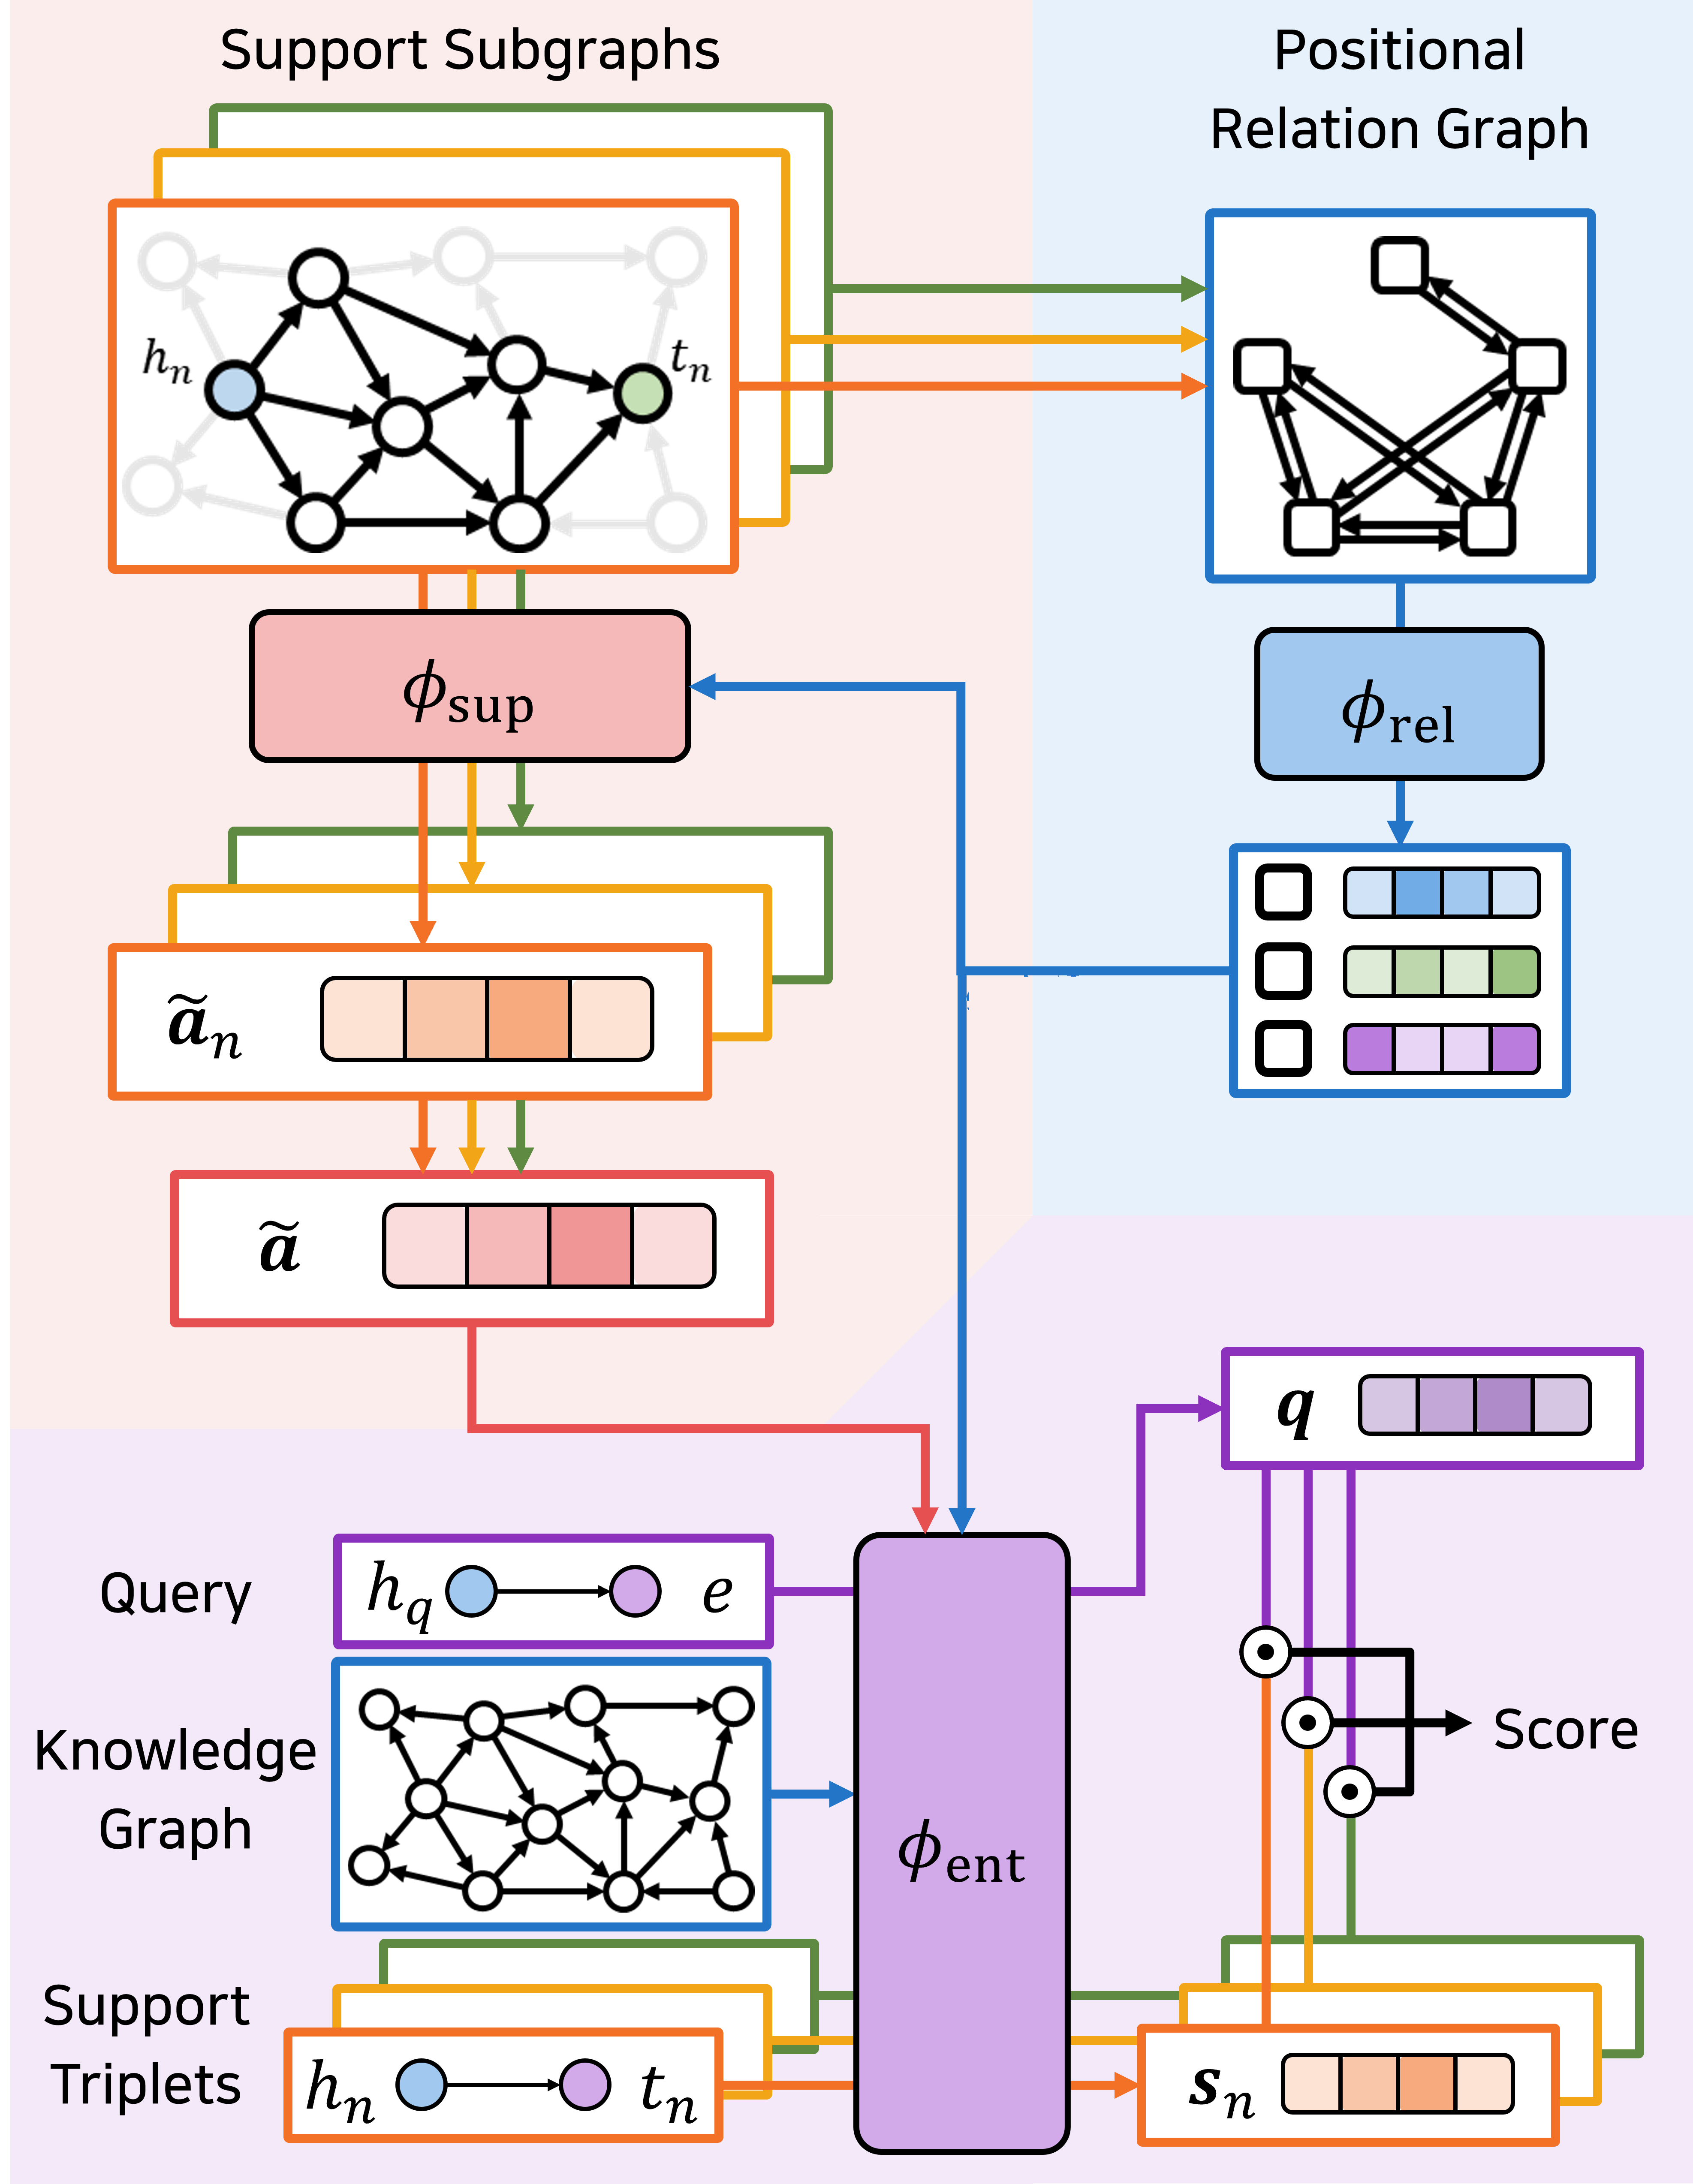
Few-shot knowledge graph completion aims to predict missing triplets involving few-shot relations, where each few-shot relation is associated with only a few examples of the relation, called support triplets. In few-shot knowledge graph completion, each few-shot task corresponds to predicting triplets for a few-shot relation. Most existing few-shot knowledge graph completion methods assume all entities and relations in knowledge graphs to be observed during training, making it challenging to deal with new entities and relations appearing at inference time. In this paper, we propose FIETA, a Few-shot InductivE knowledge graph completion method that introduces Task-Aware graph neural networks to handle few-shot tasks in knowledge graphs containing entities and relations unseen during training. Based on the local structures of support triplets, FIETA conducts task-centric modeling of relations to obtain relation representations reflecting relative positions to the few-shot relation, and performs task-guided message passing to compute entity representations optimized for each task by prioritizing triplets that are crucial in prediction. By learning to compute task-aware representations with structures, FIETA effectively handles few-shot relations on knowledge graphs with new entities and relations appearing at inference time. Experimental results show that FIETA outperforms 19 state-of-the-art baselines in various inductive scenarios.
FIETA: Few-Shot Inductive Knowledge Graph Completion via Task-Aware Graph Neural Networks
Chanyoung Chung, Minsung Hwang, Joyce Jiyoung Whang
ACM Conference on Information and Knowledge Management (CIKM) 2026
Few-shot knowledge graph completion aims to predict missing triplets involving few-shot relations, where each few-shot relation is associated with only a few examples of the relation, called support triplets. In few-shot knowledge graph completion, each few-shot task corresponds to predicting triplets for a few-shot relation. Most existing few-shot knowledge graph completion methods assume all entities and relations in knowledge graphs to be observed during training, making it challenging to deal with new entities and relations appearing at inference time. In this paper, we propose FIETA, a Few-shot InductivE knowledge graph completion method that introduces Task-Aware graph neural networks to handle few-shot tasks in knowledge graphs containing entities and relations unseen during training. Based on the local structures of support triplets, FIETA conducts task-centric modeling of relations to obtain relation representations reflecting relative positions to the few-shot relation, and performs task-guided message passing to compute entity representations optimized for each task by prioritizing triplets that are crucial in prediction. By learning to compute task-aware representations with structures, FIETA effectively handles few-shot relations on knowledge graphs with new entities and relations appearing at inference time. Experimental results show that FIETA outperforms 19 state-of-the-art baselines in various inductive scenarios.